Messaging Patterns: What They Are, When To Use Them

Whether you use Kafka, RabbitMQ, or even SMS, messaging infrastructure is neutral about what you are sending and why.  It is up to you, the developer, to decide on the contract between the producer and consumer of your messages.

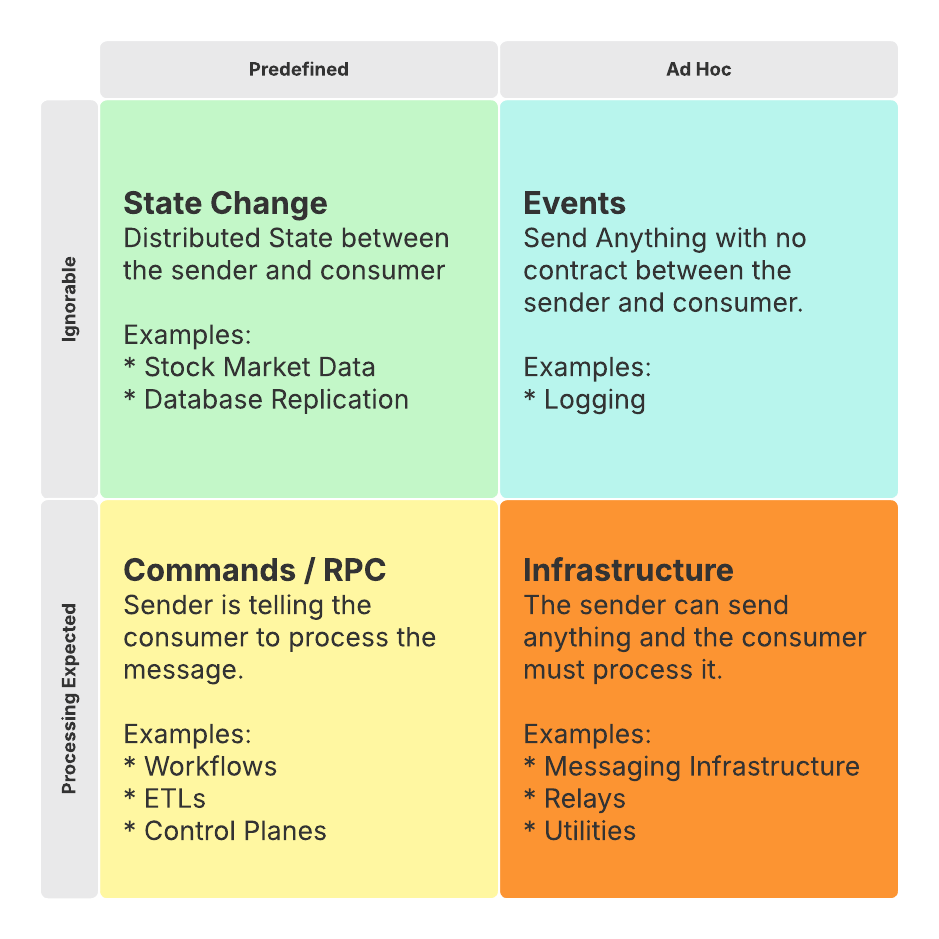
There are 2 main considerations:

  1. Are your messages Predefined or Ad Hoc?
  2. Are your messages Ignorable or is Processing Expected?
It is critical that you set appropriate expectations for your messaging structure.  Otherwise, you’ll end up with the Command-Event Anti-Pattern.

Event Pattern - Ad Hoc & Ignorable

The Event Pattern has the least structure and fewest guarantees: You publish events in any format you want, and they may or may not get consumed.

The publisher has no expectations about whether the consumer cares about the event.  The consumer has minimal expectations about the event’s structure or data.

Generally, the only time to use the Event Pattern is with logging.  

Logs are minimally structured.  You want enough structure for your logs to get consumed by your observability platform, but not enough that it is difficult to add logs in the code.

Log messages may or may not be consumed.  Most logging systems determine whether to log based on severity settings.  In production, ERROR will almost always be on, while DEBUG will almost always be off.  Those are run time decisions though, the code doesn’t have any expectations.

State Change Pattern - Structured & Ignorable

With the State Change Pattern each event represents a change to the state of the system.  The messages are highly structured so that the consumer understands how the state just changed.  However, there is no guarantee that anyone will consume the message, and no guarantees about what the consumers will do about the change.

The State Change Pattern is extremely powerful, and difficult to do correctly.

The largest State Change Messaging platforms publish market data from stock exchanges.  Each message is either a new order, a canceled order, or an execution (trade).  Trading software uses the data to determine current prices, build books, and do everything else needed to help stock traders make decisions.  

The stock market (the publisher) doesn’t have any expectations about what the consumer (the trader) on the other end will do about each message.

A more technical example of State Change is database replication.  The primary database publishes change events (called binlogs in Mysql) and the replicas database servers consume the messages to stay in sync.  From the primary server’s perspective it doesn’t matter if there are 0 replicas or 100.  Or if the replicas are only doing partial replication.  The primary server will still publish all changes.

Command Pattern - Structured with Processing Expected

In the Command Pattern, or RPC (Remote Procedure Call) each message represents an attempt to run a command or execute work.  The important difference from the Event Pattern and State Change Pattern is that the Command Pattern has expectations about the consumer’s behavior.

The publisher has the expectation that all of the messages will be processed by the consumers.  Some implementations allow the publisher to know about the consumers and direct specific messages to specific consumers, but that isn’t a requirement.

Background workers, control planes, and job queues are some of the places you would use the command pattern.

Infrastructure - Ad Hoc with Processing Expected

The final quadrant, Infrastructure, describes messaging platforms themselves.  The publisher can send whatever they want, and the platform will process it.

Because this pattern describes messaging infrastructure, there are few uses for it ON messaging infrastructure.  Having RabbitMQ tunnel through Kafka might be an interesting project, but it wouldn’t be very useful.

Beware The Command-Event Anti-Pattern

If you aren’t intentional about your messaging pattern, you will inevitably end up with the Command-Event Anti-Pattern.  This is when you have multiple, loosely defined, message structures, some of which place processing expectations on the consumer.

The Command-Event pattern makes it easy for incorrect messages to clog up the system.  It creates confusion about which messages can be ignored, and which must be processed.  You will have a muddled mess and a long hard transition to separate your message types.

Conclusion - Be Intentional About Your Messages

Remember, the messaging infrastructure will accept any structure, or no structure.  It is concerned with delivery, not processing.  So long as every consumer gets every message that it is supposed to, your infrastructure is working properly.

It is up to you, the developer, to add expectations.

How much structure do your messages need?  Can they be skipped?  Depends on what problem you are trying to solve!  If you go forward without deciding you’ll end up with a mess known as the Command-Event anti-pattern.

If you’ve got a mess, you can fix it iteratively!  Never try a rewrite!  Iteratively separate your messages onto new, problem specific, streams.
Refactoring Imports From Row At A Time To Column At A Time For Performance

This article walks you through optimizing an import process.  I’m going to lay out a simple SaaS db and api, discuss how imports emerge organically, and show you how to optimize for performance.

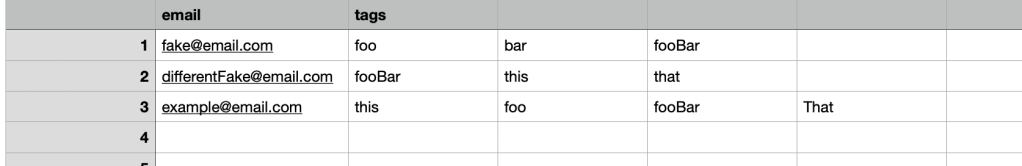
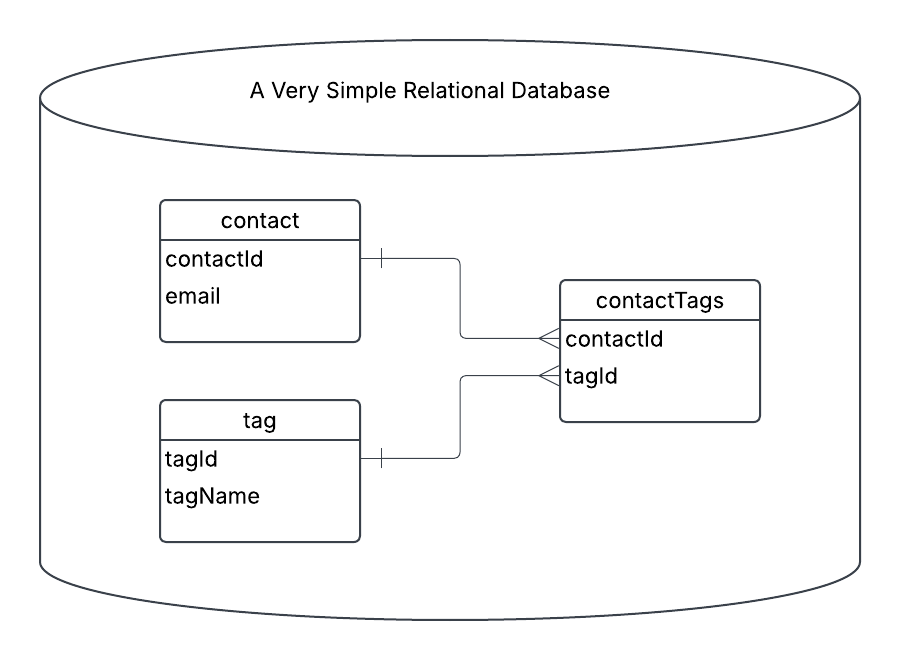
For the article, we are starting off with a simple CRM that lets you create email contacts, and add tags to them.  This is a real, but very small, piece of functionality in all CRMs, and even most SaaS.

API First

Most SaaS start with basic CRUD abilities, an endpoint to create contacts, an endpoint to create tags, and an endpoint to associate tags with contacts.  You 

[POST] /api/contact - create the contact

[POST] /api/tag - create the tag

[POST[ /api/contact/{id}/tag - create the contactTag relationship

Simple and straightforward.  Great for UIs.  Cumbersome and clunky if you aren’t a programmer.

CSV Second

Since most people aren’t programmers, and most people can export their data to CSVs, “import data from a CSV” soon emerges.

Here’s our CSV header:

Email, tag1, tag2, …, tagN

Each line starts with an email address, and then 0->N tags that should be associated with the contact.  To keep things simple we won’t be deleting any tags that are in the database, but not in the file.

When done well the customer’s file will be written somewhere like Amazon’s S3, and then processed asynchronously.  The CSV processing code will be DRY and use the same code from the API.

For each line in the file:

  1. Retrieve the existing contact’s id by email, or create a new contact
  2. For each tag
    1. Retrieve the existing tag’s id by name, or create a new tag
    2. Insert contactId, tagId into the database, if it doesn’t already exist

The code to exercise these steps already exists.

[POST] /api/contact and Retrieve the existing contact’s id by email, or create a new contact run the same code.  

[POST] /api/tag and Retrieve the existing tag’s id by name, or create a new tag are the second pair.  

[POST[ /api/contact/{id}/tag and Insert contactId, tagId into the database, if it doesn’t already exist complete the functionality.

The emergent model is great because the only new functionality is the ability to store and process the CSV file.  The business logic, how data actually gets inserted into the database, gets reused.

Big O, Performance, and Scalability

The algorithm described above has a Big O of O(n^2).  For something like an import that’s not great, but it’s also not terrible.

O(n^2) doesn’t tell you much about the real world performance or scalability of the implementation.  There are a few different implementations for the data access patterns which could result in wildly different performance characteristics.

In our simple example we look up the tagId in the database for each contact.  This mirrors the access pattern for the API.  But, we aren’t in the API, we’re in a long running process.  We could store the tag-name-to-id information in a map in memory.

Adding an in-memory cache would limit step 2a to running once-per-tag instead of once-per-tag-per-contact.  A file with a single tag per contact would save almost ⅓ of its calls.  As the number of tags increased, the savings would increase towards ½ of the db calls.

Cutting the number of DB calls in half won’t change the Big O value, but it will greatly improve performance and reduce load on your DB.

Moving From Rows To Columns

The emergent model is great because it reuses code.  One drawback is that it involves lots of trips to the database to do single inserts.  Trips to the database over a network are relatively slow.  Most databases are also optimized for fewer, larger writes.

Processing the CSV file row by row will always push you towards more, smaller, writes because the rows of the file will be relatively short.

Instead, let’s consider a “columnar” approach.

Instead of processing line by line and pushing it to the database, we’re going to sort the data in memory, and push the results to the database.

For simplicity, we will do two passes through the file.

Pass 1 looks very similar to the original process:

  1. Retrieve the existing contact’s id by email, or create a new contact.  Store the email/id relationship in a map.
  2. For each tag, retrieve the existing tag’s id by name, or create a new tag.  Store the tagName/id relationship in a map.

At the end of Pass 1, we have ensured that all contacts exist, and that all tags exist.

For Pass 2, we replace emails and tags with ids and build a single, large, insert statement like this:

Insert into contactTags (contactId, tagId) values

(1, 1), (1, 2), (1, 3),

(2, 1), (2, 3),

…


Again, simplifying and glossing over the entire subject of upserts, duplicate keys, etc.  This post is dense enough as it is.

How Much Faster Is Going A Column At A Time?

In the real world the impact will vary based on the number of rows in the table, contention, complexity, indexes, and a whole host of variables.

Instead let’s look at it by the number of queries each option requires.

Let’s pretend we were inserting a file with 100 new contacts, and each contact had the same 5 tags.

API / Basic Import

We would insert the contact, then insert the tag, then the 5 contactTags.

That is 11 operations per row - 1 contact, 5 tags, 5 contactTags.

Over 100 rows that works out to 100 contact inserts, 5 tag inserts, 495 tag lookups, 500 contactTag inserts.

That’s 1,100 Operations

Import (or API) with tag caching between rows

Adding the in-memory tag cache greatly decreases the number of operations.  We no longer need to do the redundant 495 tag lookups.

Now over the course of 100 rows it works out to 100 contact inserts, 5 tag inserts, 500 contactTag inserts.

That’s 605 Operations, at 45% reduction!

Columnar

Finally, we switched to a 2-pass columnar strategy.  Instead of doing 500 contactTag inserts, we do a single insert with 500 clauses.

Now our 100 rows become 100 contact inserts, 5 tag inserts, 1 contactTag insert.

That’s 105 Small Operations and 1 Large Operation.  That’s a 90% reduction from our initial version, and an 82% reduction from the improved version!

Reminder - that one large operation is going to take significantly longer than any one of the single inserts.  You won’t see an 82-90% reduction in processing time.  In the real world you would probably cut time by 50%, a mere 2x improvement!

The columnar work could be further optimized to be 1 large insert for contacts, 1 large tag insert, and 1 large contactTag insert.  It is more complicated because we need to get the ids, but we could get it down to as little as 5 total db operations - 3 Large Inserts and 2 key lookups.  I can cover the final technique in another post if there is interest.

Summary - Tradeoffs Make Columnar Fastest

Having your import process reuse the code from your API is a great way to start.  Because of the code reuse the only thing you have to implement is the file handling.  That keeps things simple and lets you get the feature out fast.

But, following your API’s code path is also going to be very inefficient and not scale well.

Changing strategies to favor fewer, larger, operations can reduce the number of operations by 80-90% and increase real world performance by 50% or more.

The Difference Between Rewriting And Iteratively Replacing Software 

Rewriting and Iteratively Replacing software both end with the original software being completely replaced.  Since the result is the same, it can be difficult to understand why Iterative Replacement, or TheeSeeShipping is so much more effective and less risky.

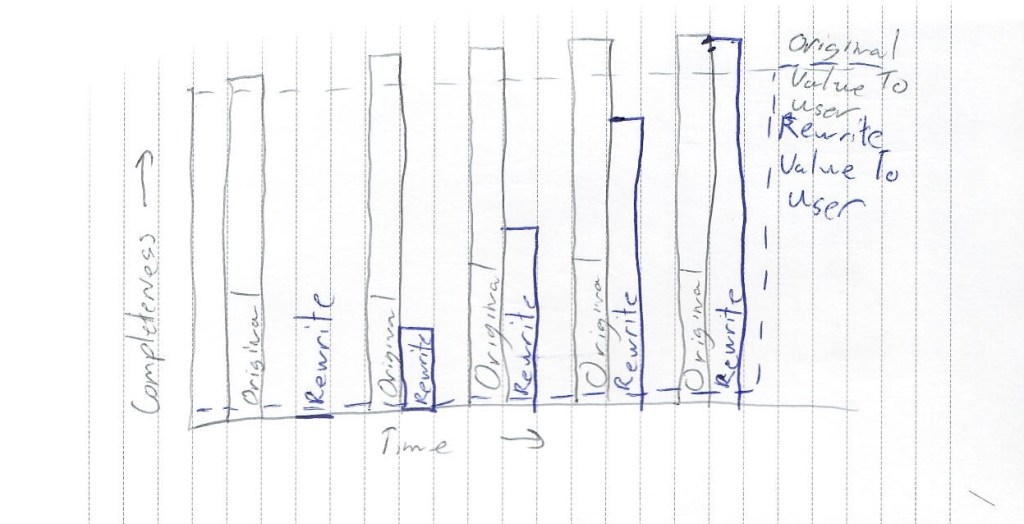
When you rewrite software you leave the original code alone and build new software that does the same thing, but better.  You start with one piece of working code, build a second piece of working code, and then stop the first.  To your users, the change happens all at once, at the end of the project.

With Iterative Replacement, you always have exactly one piece of working code.  The “bad” parts are replaced one at a time, and go into production.  At the end of every release, there is exactly one system, the one in production.  User’s experience the change gradually over time and they will see value from the project all along the way.

Both paths end with the original code being 100% replaced.  With replacement, you can see that customer value comes much earlier.  

What the graphs don’t show is the risk of the project ending before the original code has been fully removed.  If a rewrite stops before 100%, your users get nothing.

Rewrites are always more risky, because they set up an all or nothing dynamic.

Rewrite Case Study – The Three Musketeers Don’t Deliver

The Musketeer motto, “All for one, and one for all!” was a reminder that people are stronger when they work together.  Musketering works for problems as well; bringing them together makes them stronger and harder to resolve.  This is a case study where three unrelated problems: Data Latency, Data Quality, and UX were used to justify a full rewrite.

The All For One mentality, resulted in a team working hard and delivering no customer value for 12 months.  The team was only able to deliver once they pivoted from Musketering and began attacking the problems separately.

The Problem: Slow, Ugly, and Inconsistent Reports

Our reporting pages had three problems:

  1. Data Latency - The data loaded extremely slowly.  Our biggest customers could wait up to 5 minutes for a report to load.
  2. Data Quality - The data was inconsistent with itself.  The campaign report might claim that 1,000 people opened an email while a list of everyone who opened the email would only have 995 people.
  3. UX - The reports were extremely outdated.  The UX hadn’t been refreshed in 8 years and the front end code was written in Ember, a dead frontend language.  The company’s overall frontend had been iteratively migrating to React for years, reports was one of the last remaining pieces.

Addressing each issue would be a major undertaking, the team decided to tackle all 3 at once.

Insight: The three issues have very little to do with each other.  The data being slow was unrelated to the data being inconsistent.  The outdated UX had nothing to do with the available data.

Project Plan: New Data Stream, New Data Store, New UI - In 6 Weeks

The plan called for:

  • All events to be published to kafka
  • All data to be stored in Snowflake
  • A new backend service to handle requests written in Java
  • New Reports in React

At a high level the technical choices appeared reasonable.  None of the technology was new to the company.  Kafka was already in use and the new events wouldn’t add a significant amount of events onto the kafka stream.  There were several backend Java services.  More than 75% of the Ember pages had already been migrated to React.  Snowflake was available to some customers as an add-on feature.

The choices became unreasonable when all of the moving pieces were to be completed in 6 weeks.

All For One - This Is Blocked By That

The UI couldn’t proceed until the Java service was set up.  The java service couldn’t be built until there was data in Snowflake.  Data couldn’t get in Snowflake until the events were published to Kafka.

There was a natural order to the work; there was also a 6 week timeline.

Could the UI begin development using dummy data?  Absolutely!  

Would the UI require tons of rework when it came time to integrate with the Java service?  Absolutely!

The tight coupling would rattle timelines up and down the stack as team members working in isolation made new discoveries.  Each group was working on the entire scope of the project - all of the UI, all of the java service, all of the Snowflake data.  The project was set up to deliver everything, or nothing - All For One, One Release For All!

One For All!  After Nine Months, One Release

Nine months into the six week project, the reports were ready to be released to customers.

Data events were published to Kafka!  The Kafka stream was consumed by Snowflake!  The UI was in React!  There was a Java service acting as a middle layer between Snowflake and the React frontend.

Customers in the beta group were generally happy with the new reporting experience.  All was well, until the AWS bill came in and was 20x more than expected.

Tight Coupling And Tight Deadlines Left No Room For Changes

It turned out that Snowflake was the wrong tool for the job.  This is not Snowflake’s fault, any more than a hammer is to blame for hammering a screw.

The report needed unique ids in time series data, which isn’t something Snowflake is designed to support.  To get sets the developers added multiple array columns and did in memory operations to ensure that all of the array entries were unique.

This was extremely computationally expensive.

Because the project plan was supposed to deliver in 6 weeks the developers had to use an existing data store.  Because the project was late, there was no room to rethink the decision to use Snowflake.

Divide And Conquer

After 9 months of development, the new report had been released, and rolled back.  With Snowflake prohibitively expensive, the team needed a new plan.

Remember, the plan had called for:

  • All events to be published to kafka
  • All data to be stored in Snowflake
  • A new backend service to handle requests written in Java
  • New Reports in React

Without Snowflake there was no need to publish data to kafka, or a new Java service.

The team switched from Musketering to Divide And Conquer.

First, the team built new endpoints on the original service, using the original database.  It was slow, because the original system was slow.  It had inconsistencies, because the original system had inconsistencies.  The beautiful new UX was still beautiful.

Second, the team made the reports efficient and fast by adding rollup tables to the original database.  This made the report fast as well as beautiful.

Finally, the team worked on the data inconsistencies.  The inconsistencies were caused by race conditions and other concurrency issues.  There was a source of truth, and the team decided to mitigate the issue by periodically synching against the source of truth.

From start to finish the pivot took 3 months.  The final version was fast, consistent, and beautiful.  The rollup tables and periodic sync increased database load by a small amount, well within the budget.

Musketering Delays Delivery

Bringing multiple problems together helps make the case for a rewrite more compelling.  It also creates unnecessary coupling within a project.  Changes create huge delays which discourages revising the plan.

In this case almost everything written for the new reporting experience was thrown away.  Snowflake, because it was too expensive.  The Java Service and Kafka events because they existed to feed Snowflake.  Only the decision to rewrite 8 year old Ember reports in React turned out to be correct.

The opposite of Musketering is Divide and Conquer.   By taking on one problem at a time the team was able to succeed in ⅓ of the time, with a much simpler and less expensive solution.

Iteration Is Not A Speed, It’s A Journey

Iterative development is faster, but iteration isn’t a speed, it’s a journey.  Apple iterates the iPhone annually.  So do car companies.  

All iteration requires is to try and learn from the previous iteration.  Iterative development isn’t faster because iteration is fast, it’s faster because learning is part of the process.

Sometimes the iterations in software are fast.  Sometimes they are glacially slow.

As long as you are learning, and feeding the learning back into the next iteration, your software will improve.  You rarely only get one chance to release a piece of software.  Do your best, release, and learn.  Iteration isn’t a speed, it’s a journey towards better.

Things I Learned By Helping To Program A Clavinet Clone

Over the past few months I have helped my brother-in-law create a Clavinet Clone for musical keyboards.  Those of you who know me are undoubtedly laughing at the image of me creating a musical instrument because I have no rhythm, no timing, no ear, and generally musical ability of any kind.

But, I do have over 20 years of programming experience, and I haven’t worked with someone who knows “just enough to be dangerous” in a long long time.  So I was surprised by some of the lesions.

Source Control Is Not Intuitive

Older source control systems like CVS were pretty simple, but didn’t support distributed development.  Git, on the other hand, is complicated.  Each time we did a handoff, I would make a branch, develop, and merge back to main.

When I handed it back, my brother-in-law would copy the file, append “-new” and continue.  Every handover resulted in new copies of the files.  Sometimes entire directories would be copied and get “-old” added to the name.

Branching, merging, and visual diffs may be second nature to full time developers, everyone else is going to need lesions.

IDEs Will Spoil You

The code is in Kontakt scripting language, which is an internally designed and developed scripting language.  I would do my development in Sublime Text, then switch over to the UI to compile and test.

This got old after the 3rd syntax error.  A 15 second code-to-compile loop wasn’t bad back in 1992; now I just wanted syntax highlighting.

Custom Scripting Languages Make Everything Harder

Custom scripting languages make everything harder.  They make it harder on the implementer because they have to build and maintain a custom scripting language.  They make it harder on users because they have to learn a new language.

A language with minimal functionality, limited documentation, and few examples.  The biggest time waster is the lack of a testing framework.

With all that said, the Kontakt scripting language may not have been a mistake.  The same code and controls work on physical and virtual keyboards.  Getting code to work consistently on multiple hardware platforms is no small feat.

If You Can’t Have Tests, Commit Continuously

Continuous committing and diffs are a poor way to handle regressions, but they are better than nothing.  If you’re ever in this situation, make your commits as small and targeted as possible.  Regressions will still be frustratingly common and tedious, but at least you will be able to step back through your changes.

Learning Things Sounds Great!

You can buy the best sounding Clavinet Clone here!

Full disclosure: I helped program it, it belongs to my brother-in-law, and I do not get a commission.

You’ve Built A Bad Implementation Of Other Software, Now What?

The immediate response to 20 Things You Shouldn’t Build At A Midsize SaaS was, what do you do if you HAVE built some of these things?  Great question!

First, don’t panic.  We’ve all been there.  I have built some of these things myself - multiple CSV writers and parsers, a DateTime library, and an ORM.  We are all human, and we all make mistakes from time to time.

Whether you built, or are responsible for, a bad implementation of other software, what do you do now?  It depends on which of 3 buckets the implementation falls into.

It works and you don’t need to touch it

CSV parsers and writers get written a lot because they are very simple.  Yes there are edge cases when it comes to escaping strings and unicode, but mostly once you have it working, it’s “fine”.

If you don’t need to touch it, don’t!  Let sleeping dogs lie.  Ideally put a comment in the code that the next dev should replace it with a standard library instead of expanding the code.

It works ok, but it’s incomplete

This is the biggest bucket.  Implementations of DSLs, ORMs, and Frameworks usually fall into this group - the software works ok, but it is missing key features and robustness.  Observability is usually extremely lacking.

This makes the software low priority tech debt.  There’s opportunity cost from continuing to use it, a cost to replacing it, but no direct development costs.

Generally speaking, this is the kind of thing that gets ignored until you need a missing key feature.  Then the debate between continuing with the local implementation and replacing it, resumes.

The best way to approach these situations is to look at the interfaces and requirements for the replacement software, and converge the local implementation over time.  This combines regular maintenance with replacement work.   As a bonus, it lowers the cognitive load on developers by making the local implementation work more like standard offerings.

It requires continuous maintenance

Some kinds of software require continuous maintenance.  When you write your own, you have to do all the maintenance yourself.

Scripting languages are a wonderful source of Halting Problem issues.  Your customers will be excellent at creating scripts that will never exit and will consume resources until the server restarts.  The more successful you are, the worse the problem will become.

I saw a SaaS with 2 full time developers working to close all of the ways that customers were accidentally creating infinite loops with their homegrown scripting language.

I worked at a company using objective-c which had extended Apple’s compiler.  This was back in the days of installed, on-prem, software.  Every time Apple had a release, we had to warn customers not to upgrade until we could re-extend the compiler, recompile, and ship the code.

When you encounter implementations that require continuous maintenance, you have to start working to remove them immediately.  The longer they remain, the more entrenched they become.  The sunk cost fallacy will work against you in strange and insidious ways.

Iterative removal is the only real option in these cases.

No matter which bucket the badly implemented software falls into, the first step is always to recognize the problem.  If there’s already an implementation, you shouldn’t write your own without a good reason.

20 Things You Shouldn’t Build At A Midsize SaaS

I have seen developers build a lot of unnecessary and counterproductive pieces of software over the years.  Generally, developers at small to midsize SaaS companies shouldn’t build any software that doesn’t directly help them deliver a service to their customers.

Whether it was the zero interest rate period, bad management, or hubris, developers spent a lot of company money on projects that never made sense given their employer’s goals and size.  I have seen custom implementations of every type of software on this list.  None of it worked better than open source, and none offered a competitive advantage.

If you find yourself developing or managing any of these twenty types of projects, stop and seriously consider what you are doing.

  1. Scripting languages
  2. Compiler extensions
  3. Transpilers
  4. Database extensions
  5. Databases
  6. DSLs
  7. ORMs
  8. Queues
  9. Background work schedulers
  10. GraphQL
  11. Stateful REST
  12. Frontend Frameworks
  13. Backend Frameworks
  14. Servers
  15. Dependency Injectors
  16. CSV writers or parsers
  17. Cryptography Implementations
  18. Logging Libraries
  19. DateTime libraries
  20. Anything from “First principles”

There are always exceptions, if building this software has some competitive advantage, go ahead.  In general, anyone suggesting these projects is biting off more than they can chew and doesn’t fully understand the problem they are trying to solve.

Most often things start out as a quick hack - “I’ll just concatenate these strings with a comma, it will be faster than finding a full CSV library.”  Soon you’re implementing custom separators and string escaping.

If your company has done their own implementations don’t despair, iterate towards a better library!

Learning When To Stop Developing A Project

Robert Moses used lies and trickery to ensure that his projects were completed.  He loved to start projects and let pride, politics, and sunk costs pull them to completion.  Software development is notorious for grinding on and delivering projects years late that don’t solve the original problem.

SaaS project deadlines are artificial, usually the only thing that can stop a project is completion.  Even projects with no developers will shamble on, zombie-like, eating a bit of everyone’s brain as they stumble through the code.

When you find yourself confronted with a long lived, poorly defined project, start asking questions:

  1. Was there a time element to the project, and has it passed?
  2. Have the assumptions behind the project changed?
  3. Have the company’s goals changed?

Was there a time element to the project, and has it passed?

Calendars are cyclical; it’s technically never too late or too early to get ready for your industry’s high volume period.  But if you see a project to scale for Black Friday, in January, there’s a good chance that you don’t need to finish it.

Your company got through Black Friday without the project, why do you need it now?

Have the assumptions behind the project changed?

I have been involved with many “if we switch from technology X to Y, we can save a lot of money” type projects.  Less than half produced significant cost savings.  In most of the cases we knew that the savings wouldn’t materialize early in the project.  The projects kept going anyway.

It is much easier to rationalize “the cost savings may not be there, but technology Y is better” than to work out if the new tech justifies the project on technical merits.

Have the company’s goals changed?

Long running, nebulous, projects run the risk of having the company’s goals change.  I “increase performance” and “scale the system”.  But when the customer profile changes, I am often scaling the wrong part of the system.

Learning To Question Is The First Step

Before you can stop a project, you have to question the project.  Question the timing, the assumptions, and the company’s goals.

If the answers are no, it might be time to stop development.

Do You Need Permission To Write Quality Code?

A developer recently confided in me, “I wanted to write good code on this project, but when I asked my manager he said we needed to do whatever it took to hit our delivery date.”  He was explaining why he shoved his changes into the existing, giant, untestable, functions instead of refactoring and writing tests.

He asked his manager for permission to write quality code, when he didn’t get it he wrote shit code, and he missed the delivery date.

Asking permission to write quality code is the same faulty thinking that leads managers to skip testing, the idea that low quality is faster.  Low quality code is just low quality, developers won’t create it faster than high quality code.

I wrote lousy code in college because I had no idea what I was doing.  I wrote lousy code for my first year as a professional programmer because I still had no idea what I was doing.  After being on the job for about 18 months I knew I was writing lousy code but I did it anyway because that’s what I was used to doing.

After about 18 months I started copying the more effective developers and writing higher quality code.  My velocity increased with quality.  By the end of my second year as a professional programmer I was writing high quality code because that was the fastest way for me to deliver results.

When you ask for permission, you are asking for someone else to take responsibility for the decision.  If developers ever ask for permission it is a sign that they don’t believe in quality, or worse, that they don’t believe that their manager believes.

If you’re a manager and ever get asked for permission to “do it right”, ask yourself, “what has gone wrong, and how do I fix it?”

Site Footer